Chapter 8 Explaining spatial patterns
8.1 Learning objectives
By the end of this practical you should be able to:
- Explain hypothesis testing
- Execute regression in R
- Describe the assumptions associated with regression models
- Explain steps to deal with spatially autocorrelated (spatial similarity of nearby observations) residuals.
8.2 Homework
Outside of our scheduled sessions you should be doing around 12 hours of extra study per week. Feel free to follow your own GIS interests, but good places to start include the following:
Exam
Each week we will provide a short task to test your knowledge, these should be used to guide your study for the final exam.
For the task this week have a go at the practice exam questions, you should be able to answer either of the following questions:
- New York Eviction
- Graffiti mitigation
The actual exam will be distributed using the same format, so it’s vital to do this.
Reading
This week:
Chapter 2 “Linear Regression” from Hands-On Machine Learning with R by Boehmke & Greenwell (2020).
Chapter 7 “Linear Regression” from R for Health Data Science by Ewen Harrison and Riinu Pius (2021). This chapter is excellent, especially section 7.1.
Chapter 5 and 6 “Basic Regression and”Multiple Regression” from Modern Dive by Ismay and Kim (2019).
Chapter 9 Spatial regression models from Crime Mapping in R by Juanjo Medina and Reka Solymosi (2019).
Introduction to Research Methods by Eric van Holm, 2021. Chapters on regression and spatial regression
GWR a road map by Comber et al. 2022.There are related papers that have added to this discussion, such as:
Remember this is just a starting point, explore the reading list, practical and lecture for more ideas.
Doing
Read through the start of MLU Linear Regression, until learning the coefficients, which goes beyond the course here.
If you need a refresher/into to summary stats go through Teacup Giraffes
8.3 Recommended listening 🎧
Some of these practicals are long, take regular breaks and have a listen to some of our fav tunes each week.
Andy Haim. Can all play loads of instuments and just switch during live sets.
Adam Music this week - time for some big, dirty rock and roll. The Wildhearts have only gone and released a massive live album - oh yes!
8.4 Introduction
In this practical you will be introduced to a suite of different models that will allow you to test a variety of research questions and hypotheses through modelling the associations between two or more spatially reference variables.
In the worked example, we will explore the factors that might affect the average exam scores of 16 year-old across London. GSCEs are the exams taken at the end of secondary education and here have been aggregated for all pupils at their home addresses across the City for Ward geographies.
The London Data Store collates a range of other variables for each Ward and so we will see if any of these are able to help explain the patterns of exam performance that we see.
This practical will walk you through the common steps that you should go through when building a regression model using spatial data to test a stated research hypothesis; from carrying out some descriptive visualisation and summary statistics, to interpreting the results and using the outputs of the model to inform your next steps.
This practical is long and we will have two weeks to cover it.
It will first cover linear regression which you may have covered in other modules. It will then move to spatial regression models.
If you have a solid understanding of linear regression please progress to the spatial regression models section.
8.4.1 Setting up your Data
First, let’s set up R and read in some data to enable us to carry out our analysis.
#library a bunch of packages we may (or may not) use - install them first if not installed already.
library(tidyverse)
library(tmap)
library(plotly)
library(broom)## Warning: package 'broom' was built under R version 4.5.3## Warning: package 'car' was built under R version 4.5.3## Warning: package 'carData' was built under R version 4.5.3Read some ward data in from London Data Store
#download a zip file containing some boundaries we want to use
download.file("https://data.london.gov.uk/download/statistical-gis-boundary-files-london/9ba8c833-6370-4b11-abdc-314aa020d5e0/statistical-gis-boundaries-london.zip",
destfile="prac7_data/statistical-gis-boundaries-london.zip")Get the zip file and extract it
library(fs)
listfiles<-dir_info(here::here("prac7_data")) %>%
dplyr::filter(str_detect(path, ".zip")) %>%
dplyr::select(path)%>%
pull()%>%
#print out the .gz file
print()%>%
as.character()%>%
utils::unzip(exdir=here::here("prac7_data"))Look inside the zip and read in the .shp
#look what is inside the zip
Londonwards<-fs::dir_info(here::here("prac7_data",
"statistical-gis-boundaries-london",
"ESRI"))%>%
#$ means exact match
dplyr::filter(str_detect(path,
"London_Ward_CityMerged.shp$"))%>%
dplyr::select(path)%>%
dplyr::pull()%>%
#read in the file in
sf::st_read()## Reading layer `London_Ward_CityMerged' from data source
## `C:\Users\Andy\OneDrive - University College London\Teaching\CASA0005\CASA0005repo\prac7_data\statistical-gis-boundaries-london\ESRI\London_Ward_CityMerged.shp'
## using driver `ESRI Shapefile'
## Simple feature collection with 625 features and 7 fields
## Geometry type: POLYGON
## Dimension: XY
## Bounding box: xmin: 503568.2 ymin: 155850.8 xmax: 561957.5 ymax: 200933.9
## Projected CRS: OSGB36 / British National Grid
Now we are going to read in some data from the London Data Store
#read in some attribute data
LondonWardProfiles <- read_csv("https://data.london.gov.uk/download/f33fb38c-cb37-48e3-8298-84c0d3cc5a6c/772d2d64-e8c6-46cb-86f9-e52b4c7851bc/ward-profiles-excel-version.csv",
col_names = TRUE,
locale = locale(encoding = 'Latin1'))#check all of the columns have been read in correctly
Datatypelist <- LondonWardProfiles %>%
summarise_all(class) %>%
pivot_longer(everything(),
names_to="All_variables",
values_to="Variable_class")
Datatypelist8.4.1.1 Cleaning the data as you read it in
Examining the dataset as it is read in above, you can see that a number of fields in the dataset that should have been read in as numeric data, have actually been read in as character (text) data.
If you examine your data file, you will see why. In a number of columns where data are missing, rather than a blank cell, the values ‘n/a’ have been entered in instead. Where these text values appear amongst numbers, the software will automatically assume the whole column is text.
To deal with these errors, we can force read_csv to ignore these values by telling it what values to look out for that indicate missing data
#We can use readr to deal with the issues in this dataset - which are to do with text values being stored in columns containing numeric values
#read in some data - couple of things here. Read in specifying a load of likely 'n/a' values, also specify Latin1 as encoding as there is a pound sign (£) in one of the column headers - just to make things fun!
LondonWardProfiles <- read_csv("https://data.london.gov.uk/download/ward-profiles-and-atlas/772d2d64-e8c6-46cb-86f9-e52b4c7851bc/ward-profiles-excel-version.csv",
na = c("", "NA", "n/a"),
locale = locale(encoding = 'Latin1'),
col_names = TRUE)Or download it from the London data store and read it in…it’s the ward Profiles excel download.
LondonWardProfiles <- read_csv("prac7_data/ward-profiles-excel-version.csv",
na = c("", "NA", "n/a"),
locale = locale(encoding = 'Latin1'),
col_names = TRUE)## Rows: 660 Columns: 67
## ── Column specification ────────────────────────────────────────────
## Delimiter: ","
## chr (3): Ward name, Old code, New code
## dbl (64): Population - 2015, Children aged 0-15 - 2015, Working-age (16-64) ...
##
## ℹ Use `spec()` to retrieve the full column specification for this data.
## ℹ Specify the column types or set `show_col_types = FALSE` to quiet this message.#check all of the columns have been read in correctly
Datatypelist <- LondonWardProfiles %>%
summarise_all(class) %>%
pivot_longer(everything(),
names_to="All_variables",
values_to="Variable_class")
DatatypelistNow you have read in both your boundary data and your attribute data, you need to merge the two together using a common ID. In this case, we can use the ward codes to achieve the join
#merge boundaries and data
LonWardProfiles <- Londonwards%>%
left_join(.,
LondonWardProfiles,
by = c("GSS_CODE" = "New code"))
#let's map our dependent variable to see if the join has worked:
tmap_mode("plot")
qtm(LonWardProfiles,
fill = "Average GCSE capped point scores - 2014",
fill.palette = "Blues")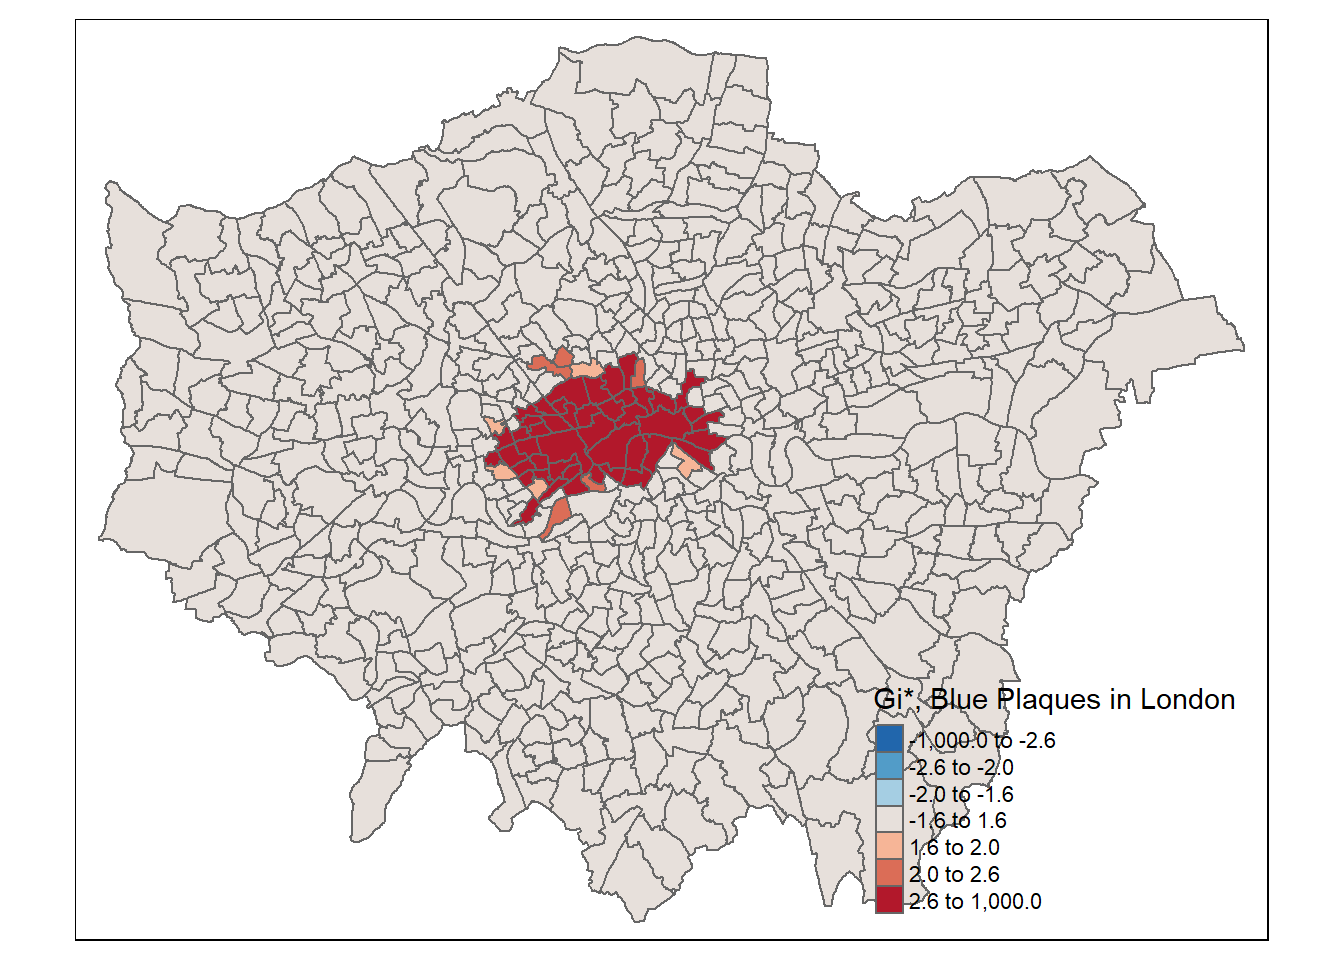
8.4.1.2 Additional Data
In addition to our main datasets, it might also be useful to add some contextual data. While our exam results have been recorded at the home address of students, most students would have attended one of the schools in the City.
Let’s add some schools data as well. In the st_as_sf function x is longitude, y is latitude.
#might be a good idea to see where the secondary schools are in London too
london_schools <- read_csv("https://data.london.gov.uk/download/146392df-b051-42ad-b8ec-454e440f0f8b/57046151-39a0-45d9-8dc0-27ea7fd02de8/all_schools_xy_2016.csv")
#from the coordinate values stored in the x and y columns, which look like they are latitude and longitude values, create a new points dataset
lon_schools_sf <- st_as_sf(london_schools,
coords = c("x","y"),
crs = 4326)
lond_sec_schools_sf <- lon_schools_sf %>%
filter(PHASE=="Secondary")
tmap_mode("plot")
qtm(lond_sec_schools_sf, size=0.2)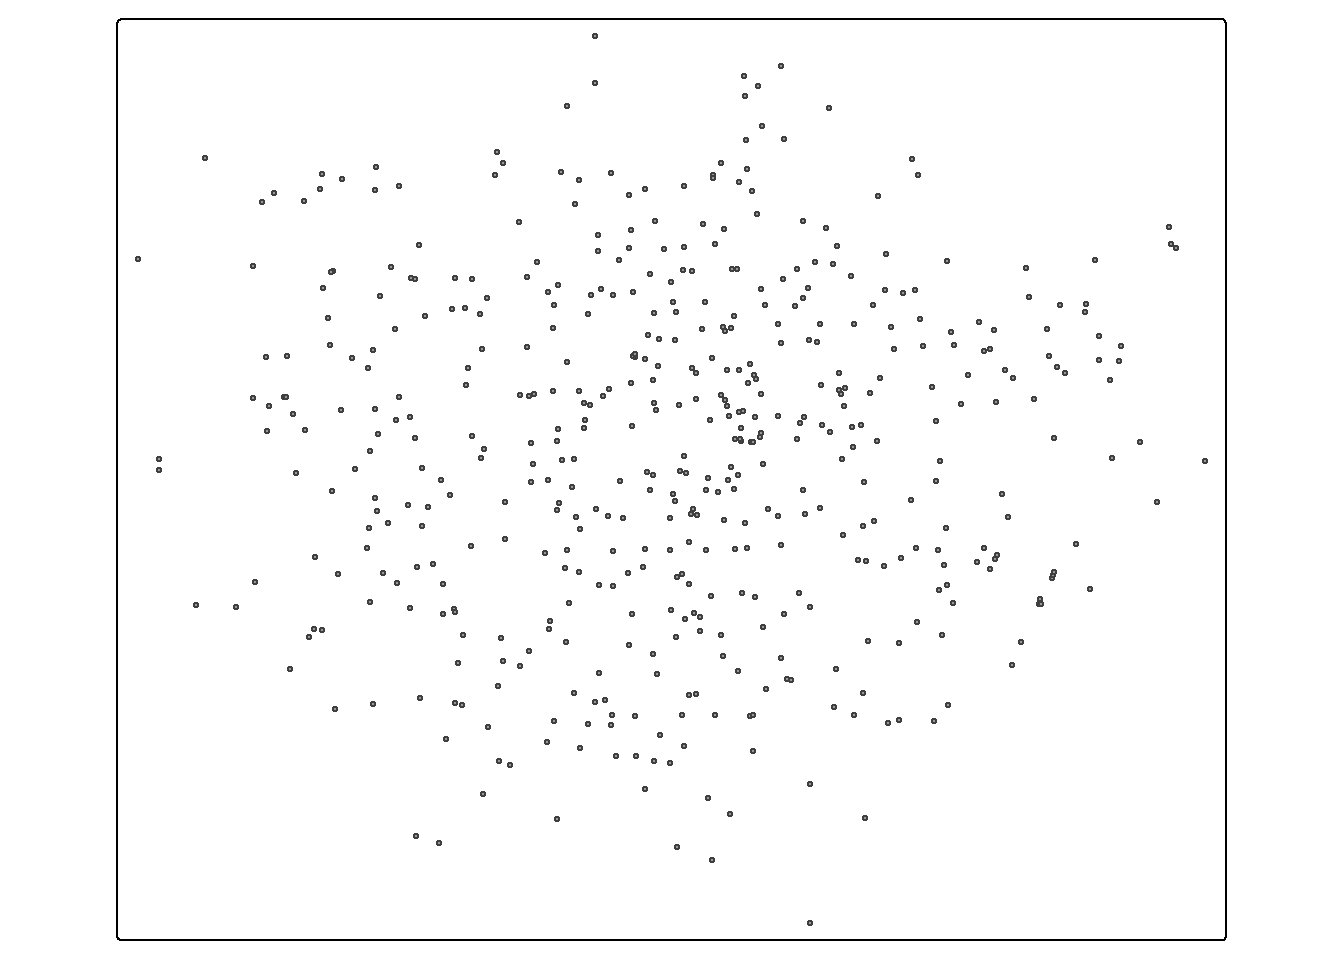
8.5 Analysing GCSE exam performance - testing a research hypothesis
To explore the factors that might influence GCSE exam performance in London, we are going to run a series of different regression models. A regression model is simply the expression of a linear relationship between our outcome variable (Average GCSE score in each Ward in London) and another variable or several variables that might explain this outcome.
8.5.1 Research Question and Hypothesis
Examining the spatial distribution of GSCE point scores in the map above, it is clear that there is variation across the city. My research question is:
What are the factors that might lead to variation in Average GCSE point scores across the city?
My research hypothesis that I am going to test is that there are other observable factors occurring in Wards in London that might affect the average GCSE scores of students living in those areas.
In inferential statistics, we cannot definitively prove a hypothesis is true, but we can seek to disprove that there is absolutely nothing of interest occurring or no association between variables. The null hypothesis that I am going to test empirically with some models is that there is no relationship between exam scores and other observed variables across London.
8.5.2 Regression Basics
For those of you who know a bit about regression, you might want to skip down to the next section. However, if you are new to regression or would like a refresher, read on…
The linear relationship in a regression model is probably most easily explained using a scatter plot…
q <- qplot(x = `Unauthorised Absence in All Schools (%) - 2013`,
y = `Average GCSE capped point scores - 2014`,
data=LonWardProfiles)## Warning: `qplot()` was deprecated in ggplot2 3.4.0.
## This warning is displayed once per session.
## Call `lifecycle::last_lifecycle_warnings()` to see where this
## warning was generated.#plot with a regression line - note, I've added some jitter here as the x-scale is rounded
q + stat_smooth(method="lm", se=FALSE, size=1) +
geom_jitter()
Here, I have plotted the average GCSE point score for each Ward in London against another variable in the dataset that I think might be influential: the % of school days lost to unauthorised absences in each ward.
Remember that my null hypothesis would be that there is no relationship between GCSE scores and unauthorised absence from school. If this null hypothesis was true, then I would not expect to see any pattern in the cloud of points plotted above.
As it is, the scatter plot shows that, generally, as the \(x\) axis independent variable (unauthorised absence) goes up, our \(y\) axis dependent variable (GCSE point score) goes down. This is not a random cloud of points, but something that indicates there could be a relationshp here and so I might be looking to reject my null hypothesis.
Some conventions - In a regression equation, the dependent variable is always labelled \(y\) and shown on the \(y\) axis of a graph, the predictor or independent variable(s) is(are) always shown on the \(x\) axis.
I have added a blue line of best-fit - this is the line that can be drawn by minimising the sum of the squared differences between the line and the residuals. The residuals are all of the dots not falling exactly on the blue line. An algorithm known as ‘ordinary least squares’ (OLS) is used to draw this line and it simply tries a selection of different lines until the sum of the squared divations between all of the residuals and the blue line is minimised, leaving the final solution.
As a general rule, the better the blue line is at summarising the relationship between \(y\) and \(x\), the better the model.
The equation for the blue line in the graph above can be written:
\[y_i = \beta_0 + \beta_1x_i + \epsilon_i\]
where:
\(\beta_0\) is the intercept (the value of \(y\) when \(x = 0\) - somewhere around 370 on the graph above);
\(\beta_1\) is sometimes referred to as the ‘slope’ parameter and is simply the change in the value of \(y\) for a 1 unit change in the value of \(x\) (the slope of the blue line) - reading the graph above, the change in the value of \(y\) reading between 1.0 and 2.0 on the \(x\) axis looks to be around -40.
\(\epsilon_i\) is a random error term (positive or negative) that should sum to 0 - esentially, if you add all of the vertical differences between the blue line and all of the residuals, it should sum to 0.
Any value of \(y\) along the blue line can be modelled using the corresponding value of \(x\) and these parameter values. Examining the graph above we would expect the average GCSE point score for a student living in a Ward where 0.5% of school days per year were missed, to equal around 350, but we can confirm this by plugging the \(\beta\) parameter values and the value of \(x\) into equation (1):
## [1] 3508.5.3 Running a Regression Model in R
In the graph above, I used a method called ‘lm’ in the stat_smooth() function in ggplot2 to draw the regression line. ‘lm’ stands for ‘linear model’ and is a standard function in R for running linear regression models. Use the help system to find out more about lm - ?lm
Below is the code that could be used to draw the blue line in our scatter plot. Note, the tilde ~ symbol means “is modelled by”.
First though, we’re going to clean up all our data names with Janitor then select what we want.
#run the linear regression model and store its outputs in an object called model1
Regressiondata<- LonWardProfiles%>%
clean_names()%>%
dplyr::select(average_gcse_capped_point_scores_2014,
unauthorised_absence_in_all_schools_percent_2013)
#now model
model1 <- Regressiondata %>%
lm(average_gcse_capped_point_scores_2014 ~
unauthorised_absence_in_all_schools_percent_2013,
data=.)Let’s have a closer look at our model…
##
## Call:
## lm(formula = average_gcse_capped_point_scores_2014 ~ unauthorised_absence_in_all_schools_percent_2013,
## data = .)
##
## Residuals:
## Min 1Q Median 3Q Max
## -59.753 -10.223 -1.063 8.547 61.842
##
## Coefficients:
## Estimate Std. Error t value
## (Intercept) 371.471 2.165 171.6
## unauthorised_absence_in_all_schools_percent_2013 -41.237 1.927 -21.4
## Pr(>|t|)
## (Intercept) <2e-16 ***
## unauthorised_absence_in_all_schools_percent_2013 <2e-16 ***
## ---
## Signif. codes: 0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
##
## Residual standard error: 16.39 on 624 degrees of freedom
## Multiple R-squared: 0.4233, Adjusted R-squared: 0.4224
## F-statistic: 458 on 1 and 624 DF, p-value: < 2.2e-168.5.3.1 Interpreting and using the model outputs
In running a regression model, we are effectively trying to test (disprove) our null hypothesis. If our null hypothesis was true, then we would expect our coefficients to = 0.
In the output summary of the model above, there are a number of features you should pay attention to:
Coefficient Estimates - these are the \(\beta_0\) (intercept) and \(\beta_1\) (slope) parameter estimates from Equation 1. You will notice that at \(\beta_0 = 371.471\) and \(\beta_1 = -41.237\) they are pretty close to the estimates of 370 and -40 that we read from the graph earlier, but more precise.
Coefficient Standard Errors - these represent the average amount the coefficient varies from the average value of the dependent variable (its standard deviation). So, for a 1% increase in unauthorised absence from school, while the model says we might expect GSCE scores to drop by -41.2 points, this might vary, on average, by about 1.9 points. As a rule of thumb, we are looking for a lower value in the standard error relative to the size of the coefficient.
Note that is the coefficient represents a one unit change, here it is %, as the variable is % unauthorized absence in school So one unit is a 1% change…
Coefficient t-value - this is the value of the coefficient divided by the standard error and so can be thought of as a kind of standardised coefficient value. The larger (either positive or negative) the value the greater the relative effect that particular independent variable is having on the dependent variable (this is perhaps more useful when we have several independent variables in the model) .
Coefficient p-value - Pr(>|t|) - the p-value is a measure of significance. There is lots of debate about p-values which I won’t go into here, but essentially it refers to the probability of getting a coefficient as large as the one observed in a set of random data. p-values can be thought of as percentages, so if we have a p-value of 0.5, then there is a 5% chance that our coefficient could have occurred in some random data, or put another way, a 95% chance that out coefficient could have only occurred in our data. As a rule of thumb, the smaller the p-value, the more significant that variable is in the story and the smaller the chance that the relationship being observed is just random. Generally, statisticians use 5% or 0.05 as the acceptable cut-off for statistical significance - anything greater than that we should be a little sceptical about.
In r the codes ***, **, **, . are used to indicate significance. We generally want at least a single * next to our coefficient for it to be worth considering.
R-Squared - This can be thought of as an indication of how good your model is - a measure of ‘goodness-of-fit’ (of which there are a number of others). \(r^2\) is quite an intuitite measure of fit as it ranges between 0 and 1 and can be thought of as the % of variation in the dependent variable (in our case GCSE score) explained by variation in the independent variable(s). In our example, an \(r^2\) value of 0.42 indicates that around 42% of the variation in GCSE scores can be explained by variation in unathorised absence from school. In other words, this is quite a good model. The \(r^2\) value will increase as more independent explanatory variables are added into the model, so where this might be an issue, the adjusted r-squared value can be used to account for this affect
8.5.3.2 broom
The output from the linear regression model is messy and like all things R mess can be tidied, in this case with a broom! Or the package broom which is also party of the package tidymodels.
Here let’s load broom and tidy our output…you will need to either install tidymodels or broom. The tidy() function will just make a tibble or the statistical findings from the model!
## # A tibble: 2 × 5
## term estimate std.error statistic p.value
## <chr> <dbl> <dbl> <dbl> <dbl>
## 1 (Intercept) 371. 2.16 172. 0
## 2 unauthorised_absence_in_all_schools_per… -41.2 1.93 -21.4 1.27e-76We can also use glance() from broom to get a bit more summary information, such as \(r^2\) and the adjusted r-squared value.
## # A tibble: 1 × 12
## r.squared adj.r.squared sigma statistic p.value df logLik AIC BIC
## <dbl> <dbl> <dbl> <dbl> <dbl> <dbl> <dbl> <dbl> <dbl>
## 1 0.423 0.422 16.4 458. 1.27e-76 1 -2638. 5282. 5296.
## # ℹ 3 more variables: deviance <dbl>, df.residual <int>, nobs <int>But wait? Didn’t we try to model our GCSE values based on our unauthorised absence variable? Can we see those predictions for each point, yes, yes we can…with the tidypredict_to_column() function from tidypredict, which adds the fit column in the following code.
## Warning: package 'tidypredict' was built under R version 4.5.3## Simple feature collection with 626 features and 3 fields
## Geometry type: POLYGON
## Dimension: XY
## Bounding box: xmin: 503568.2 ymin: 155850.8 xmax: 561957.5 ymax: 200933.9
## Projected CRS: OSGB36 / British National Grid
## First 10 features:
## average_gcse_capped_point_scores_2014
## 1 321.3
## 2 337.5
## 3 342.7
## 4 353.3
## 5 372.3
## 6 339.8
## 7 307.1
## 8 361.6
## 9 347.0
## 10 336.4
## unauthorised_absence_in_all_schools_percent_2013
## 1 0.8
## 2 0.7
## 3 0.5
## 4 0.4
## 5 0.7
## 6 0.9
## 7 0.8
## 8 0.6
## 9 0.7
## 10 0.5
## geometry fit
## 1 POLYGON ((516401.6 160201.8... 338.4815
## 2 POLYGON ((517829.6 165447.1... 342.6052
## 3 POLYGON ((518107.5 167303.4... 350.8525
## 4 POLYGON ((520480 166909.8, ... 354.9762
## 5 POLYGON ((522071 168144.9, ... 342.6052
## 6 POLYGON ((522007.6 169297.3... 334.3579
## 7 POLYGON ((517175.3 164077.3... 338.4815
## 8 POLYGON ((517469.3 166878.5... 346.7289
## 9 POLYGON ((522231.1 166015, ... 342.6052
## 10 POLYGON ((517460.6 167802.9... 350.85258.5.4 tidymodels
Before we move on it’s worth pointing out that a new iteration of modelling is being developed through tidymodels…the benefit of this is that we can easily change the modelling method or as they term it…engine…(e.g. to RandomForest)
## Warning: package 'tidymodels' was built under R version 4.5.3## Warning: package 'dials' was built under R version 4.5.3## Warning: package 'infer' was built under R version 4.5.3## Warning: package 'modeldata' was built under R version 4.5.3## Warning: package 'parsnip' was built under R version 4.5.3## Warning: package 'recipes' was built under R version 4.5.3## Warning: package 'rsample' was built under R version 4.5.3## Warning: package 'tune' was built under R version 4.5.3## Warning: package 'yardstick' was built under R version 4.5.3# set the model
lm_mod <- linear_reg()
# fit the model
lm_fit <-
lm_mod %>%
fit(average_gcse_capped_point_scores_2014 ~
unauthorised_absence_in_all_schools_percent_2013,
data=Regressiondata)
# we cover tidy and glance in a minute...
tidy(lm_fit)## # A tibble: 2 × 5
## term estimate std.error statistic p.value
## <chr> <dbl> <dbl> <dbl> <dbl>
## 1 (Intercept) 371. 2.16 172. 0
## 2 unauthorised_absence_in_all_schools_per… -41.2 1.93 -21.4 1.27e-76## # A tibble: 1 × 12
## r.squared adj.r.squared sigma statistic p.value df logLik AIC BIC
## <dbl> <dbl> <dbl> <dbl> <dbl> <dbl> <dbl> <dbl> <dbl>
## 1 0.423 0.422 16.4 458. 1.27e-76 1 -2638. 5282. 5296.
## # ℹ 3 more variables: deviance <dbl>, df.residual <int>, nobs <int>However at the moment we can’t do spatial modelling using tidymodels…but this is probably coming soon.
8.5.5 Bootstrap resampling
If we only fit our model once, how can we be confident about that estimate? Bootstrap resampling is where we take the original dataset and select random data points from within it, but in order to keep it the same size as the original dataset some records are duplicated. This is known as bootstrap resampling by replacement. We used to briefly cover this within this practical but have recently removed it. If you wish to explore it then consult the bootstrap resampling section from previous years, but this is not a requirement and only for interest.
8.5.6 Variables
Common questions i get asked about regression that are not within scope of the module, but there are some resources here should you want to use them in future (e.g. dissertations):
Must my variables be normally distrubuted
The right answer is no. Although different academics have different responses. If the data is not normally distributed the residuals may be not normally distributed (hence why i suggest it here), although this could be an issue with the model / independent variables selected and not the data. They residuals may well be normally distributed, but could vary (meaning we have hetroscedasticity) which we discuss later on. So you might only want to transform the data if it is very skewed.
How do i select my variables
Either with logic and reasoning (e.g. in the exam), with the support of academic literature or methods such as best subset regression, k-fold cross validation or gradient descent. It does not form part of this module. Other regression methods such as Ridge, LASSO and elastic net regression can reduce the influence of variables that are not useful in the model. But again, this is beyond the scope of this module.
Should i center and scale my data
This means giving all your variables a mean of 0 (centering) and standard deviation of 1 (scaling). This is done through subtracting the mean from each value and dividing by the standard deviation (this latter part is often called standardizing). There is much debate on when to do this. Neal Goldstein has a good list of why and when to do this and this blog provides a nice explanation. Typically reasons might include multicollinearity and large differences in data ranges. To interpret the coefficient of this it you can transform them back. But this does not form part of this module.
What is confounding
A confounding variable is where an extraneous variable (an external to your model variable) is related to both the dependent and independent (those used to predict the dependent) variables.
An example from Scribbr is that if you are modelling sunburn using ice cream consumption then temperature will influence both of these variables.
There are several ways to solve this explained in Scribbr article, one approach is to include the variables as control variables (this is not of interest in the study but must be accounted for) in the model so you can account for them.
For a confounding variable it must be:
- correlated with other independent variables (see Assumption 3 - No Multicolinearity in the independent variables)
- causally related to the dependent - known to influence the dependent variable
However, in our work, if our independent variables are correlated we might remove the one that has least influence on the model to resolve this situation.
For details on regression diagnostics see testing the assumptions of linear regression
8.5.8 Assumption 1 - There is a linear relationship between the dependent and independent variables
The best way to test for this assumption is to plot a scatter plot similar to the one created earlier. It may not always be practical to create a series of scatter plots, so one quick way to check that a linear relationship is probable is to look at the frequency distributions of the variables. If they are normally distributed, then there is a good chance that if the two variables are in some way correlated, this will be a linear relationship.
For example, look at the frequency distributions of our two variables earlier:
#let's check the distribution of these variables first
ggplot(LonWardProfiles, aes(x=`Average GCSE capped point scores - 2014`)) +
geom_histogram(aes(y = ..density..),
binwidth = 5) +
geom_density(colour="red",
size=1,
adjust=1)## Warning: The dot-dot notation (`..density..`) was deprecated in ggplot2
## 3.4.0.
## ℹ Please use `after_stat(density)` instead.
## This warning is displayed once per session.
## Call `lifecycle::last_lifecycle_warnings()` to see where this
## warning was generated.
Here, adding ..density.. means that the histogram is a density plot, this plots the chance that any value in the data is equal to that value.
ggplot(LonWardProfiles, aes(x=`Unauthorised Absence in All Schools (%) - 2013`)) +
geom_histogram(aes(y = ..density..),
binwidth = 0.1) +
geom_density(colour="red",
size=1,
adjust=1)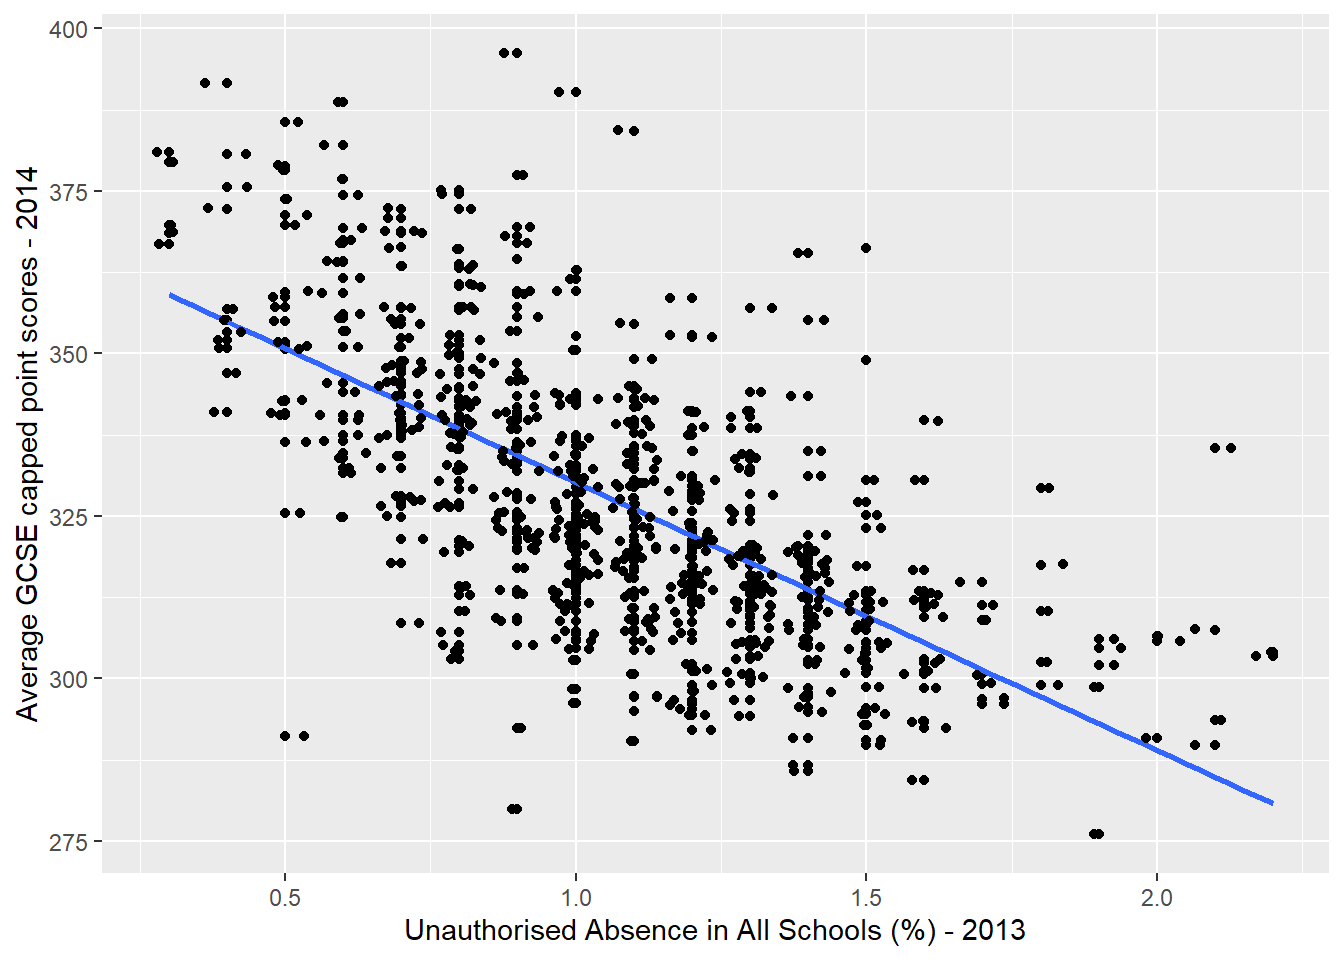
We would describe both of these distribution as being relatively ‘normally’ or gaussian disributed, and thus more likely to have a linear correlation (if they are indeed associated).
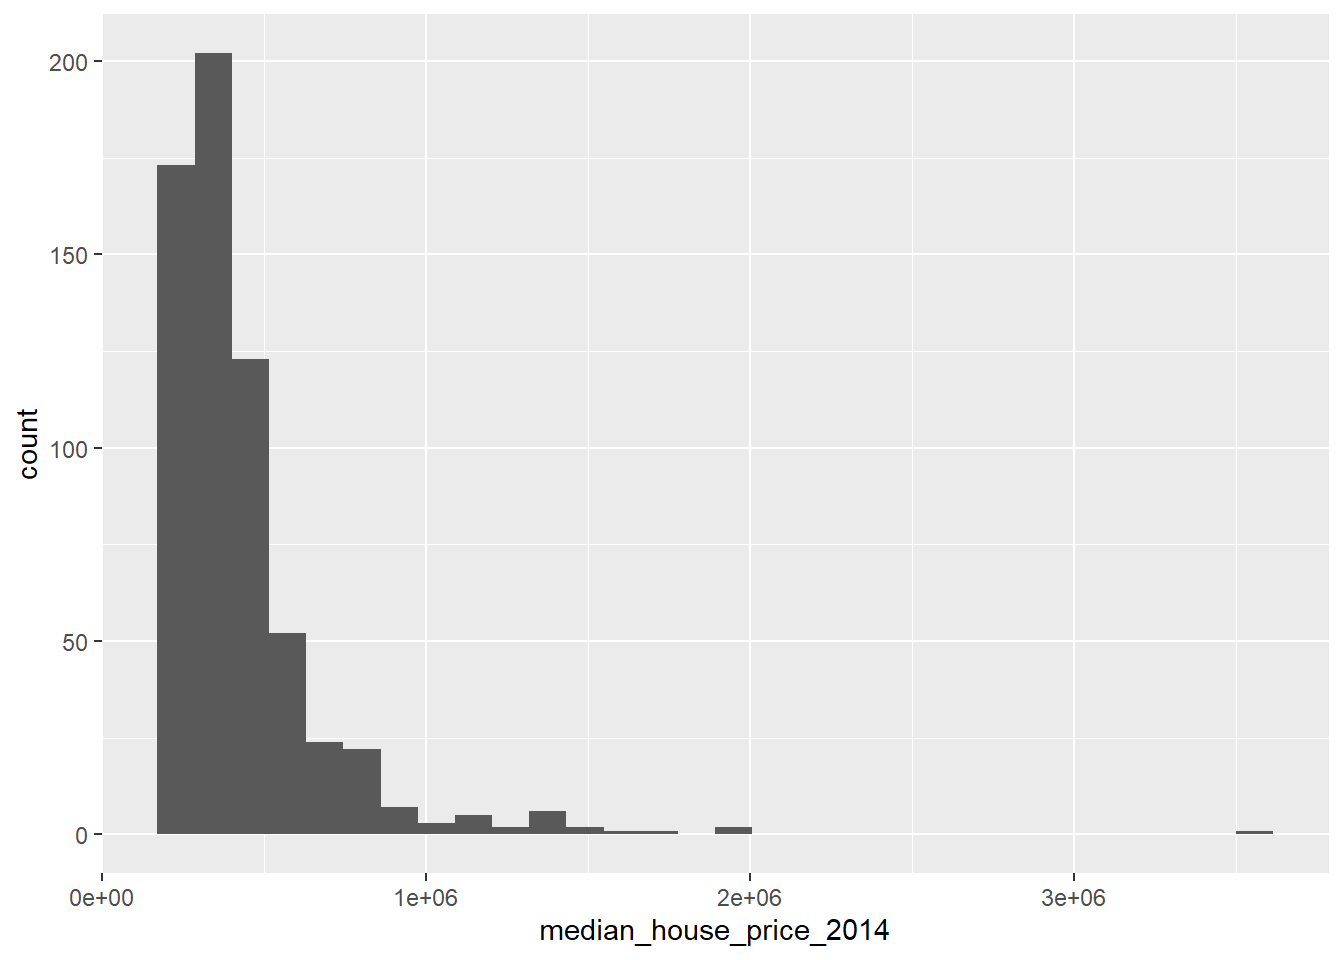
Contrast this with the median house price variable:
Note in the code below I’ve renamed the Median House Price (£) - 2014 column manually. The data provider changed this variable to be called median_house_price<c2>2014 around the 21/10/22 and then recently corrected it back to Median House Price (£) - 2014 (November 2022). However, when i render this book it still doesn’t like it. So to fix this i just manually renamed the column and then used clean_names() for the rest of the columns. Good code is code that works and doesn’t always need to be pretty / clean
library(ggplot2)
# from 21/10 there is an error on the website with
# median_house_price_2014 being called median_house_price<c2>2014
# this was corrected around 23/11 but can be corrected with rename..
LonWardProfiles <- LonWardProfiles %>%
#try removing this line to see if it works...
dplyr::rename(median_house_price_2014 =`Median House Price (£) - 2014`)%>%
janitor::clean_names()
ggplot(LonWardProfiles, aes(x=median_house_price_2014)) +
geom_histogram()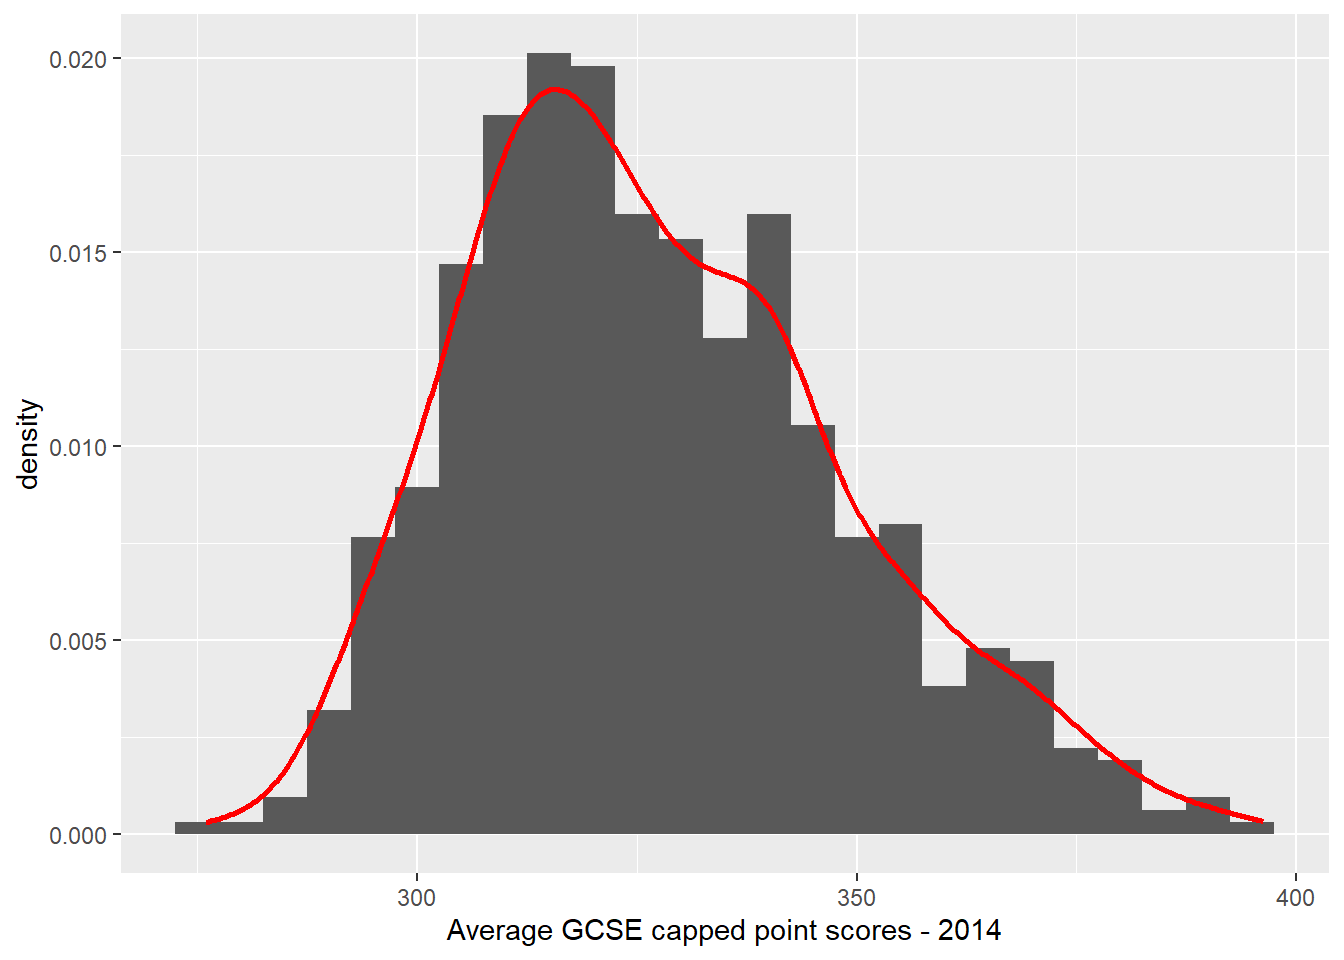
We would describe this as a not normal and/or positively ‘skewed’ distribution, i.e. there are more observations towards the lower end of the average house prices observed in the city, however there is a long tail to the distribution, i.e. there are a small number of wards where the average house price is very large indeed.
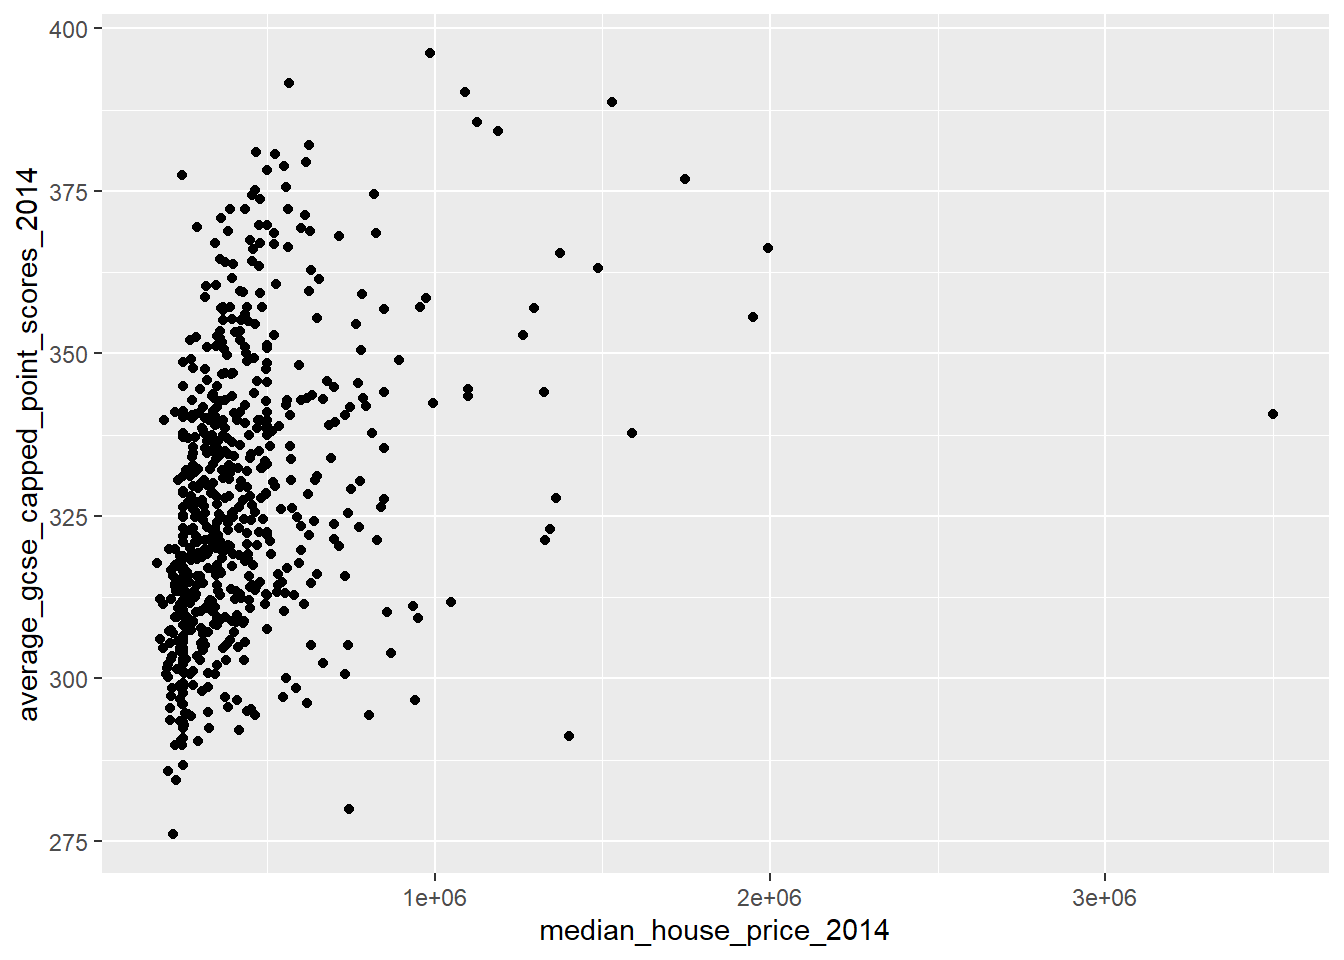
If we plot the raw house price variable against GCSE scores, we get the following scatter plot:

This indicates that we do not have a linear relationship, indeed it suggests that this might be a curvilinear relationship.
8.5.8.1 Transforming variables
One way that we might be able to achieve a linear relationship between our two variables is to transform the non-normally distributed variable so that it is more normally distributed.
There is some debate as to whether this is a wise thing to do as, amongst other things, the coefficients for transformed variables are much harder to interpret, however, we will have a go here to see if it makes a difference.
Tukey’s ladder of transformations
You might be asking how we could go about transforming our variables. In 1977, Tukey described a series of power transformations that could be applied to a variable to alter its frequency distribution.
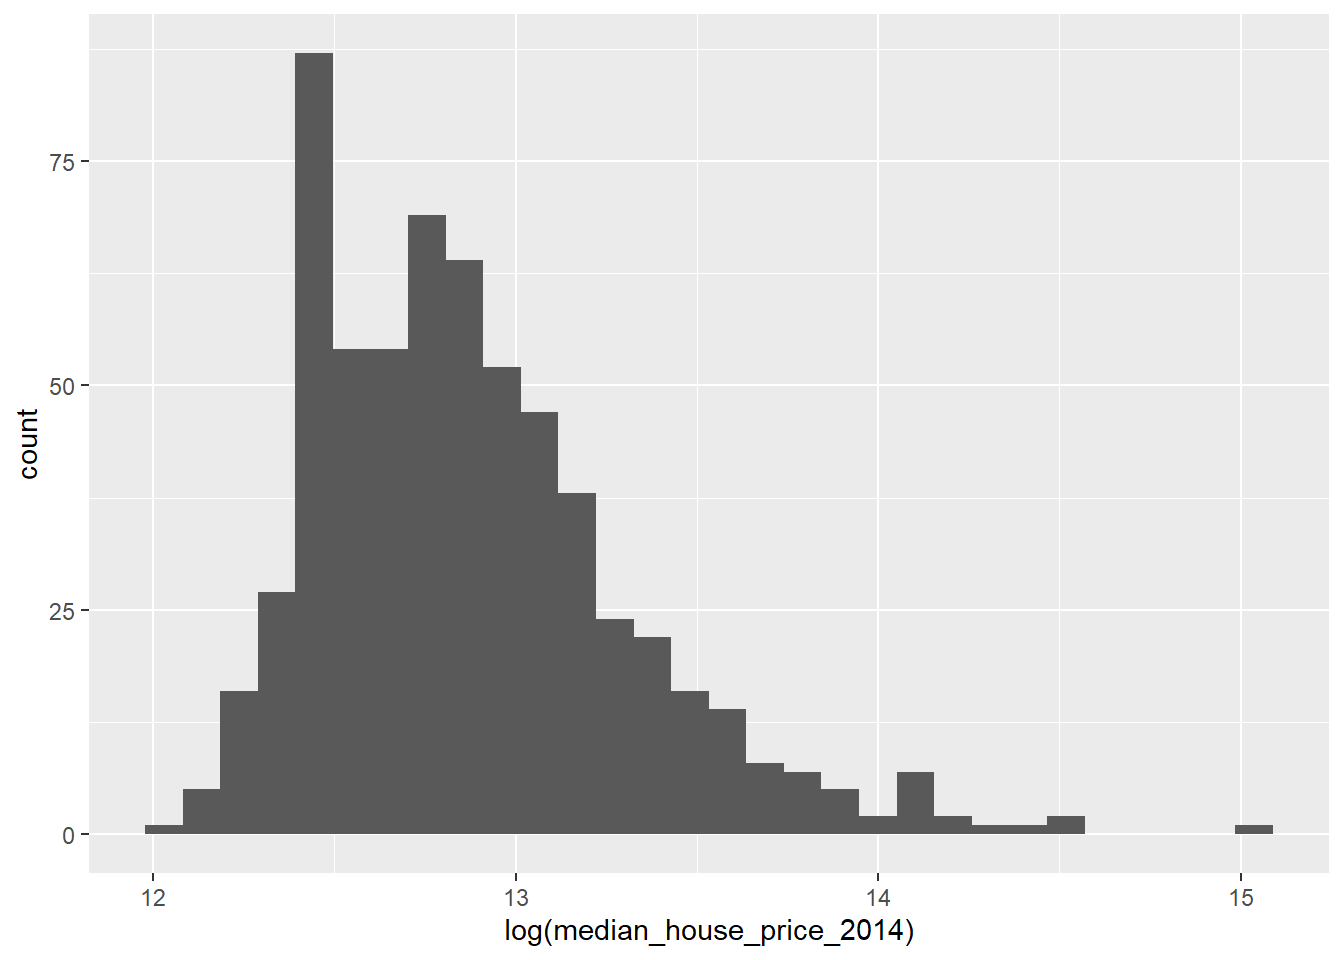
In regression analysis, you analysts will frequently take the log of a variable to change its distribution, but this is a little crude and may not result in a completely normal distribution. For example, we can take the log of the house price variable:

This looks a little more like a normal distribution, but it is still a little skewed.
Fortunately in R, we can use the symbox() function in the car package to try a range of transfomations along Tukey’s ladder:
Observing the plot above, it appears that raising our house price variable to the power of -1 should lead to a more normal distribution:
qplot(x = (median_house_price_2014)^-1,
y = average_gcse_capped_point_scores_2014,
data=LonWardProfiles)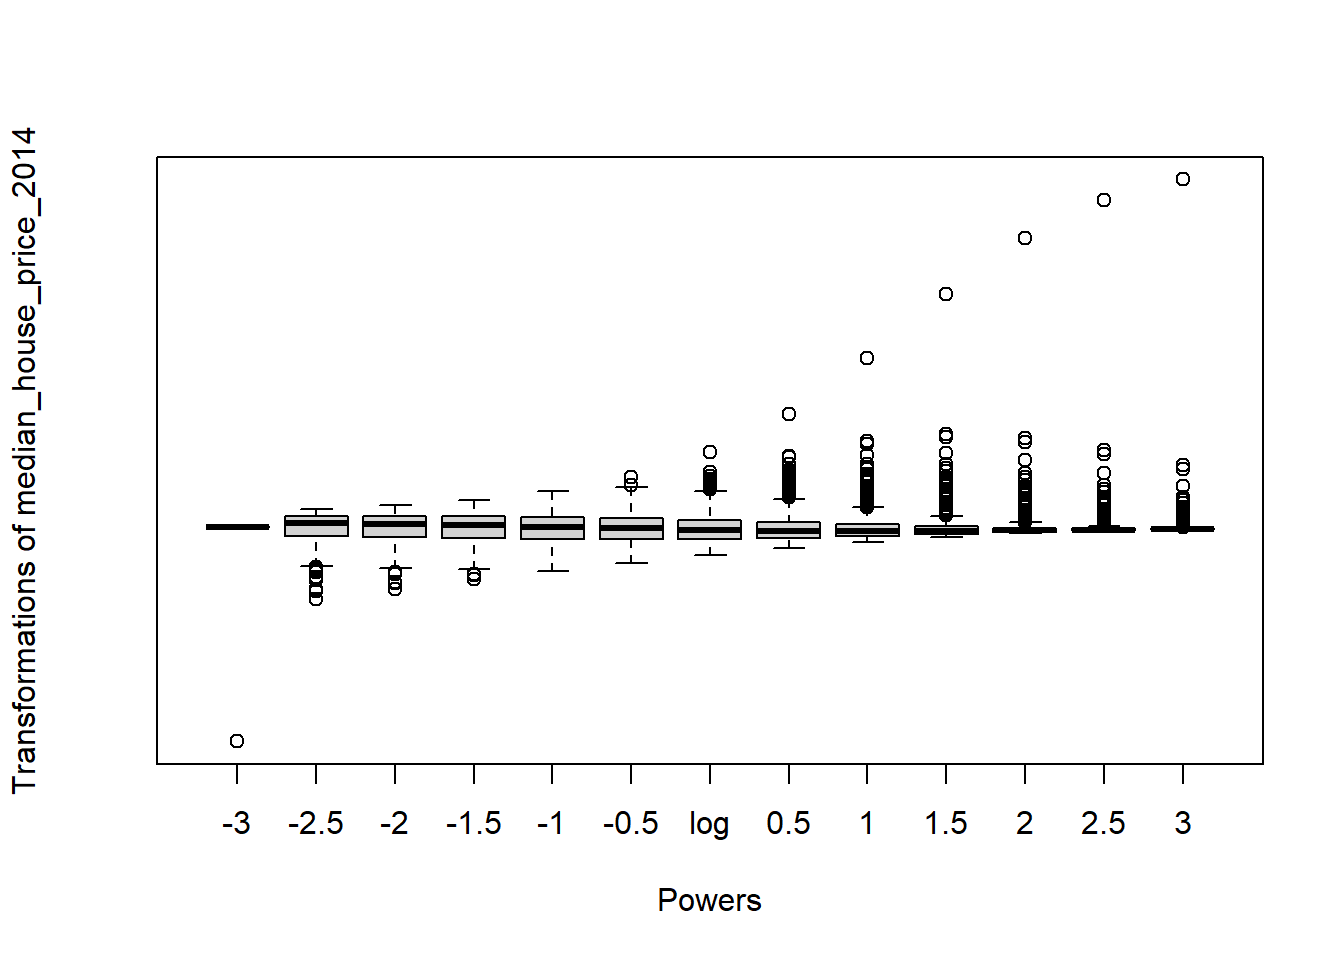
Compare this with the logged transformation:
qplot(x = log(median_house_price_2014),
y = average_gcse_capped_point_scores_2014,
data=LonWardProfiles)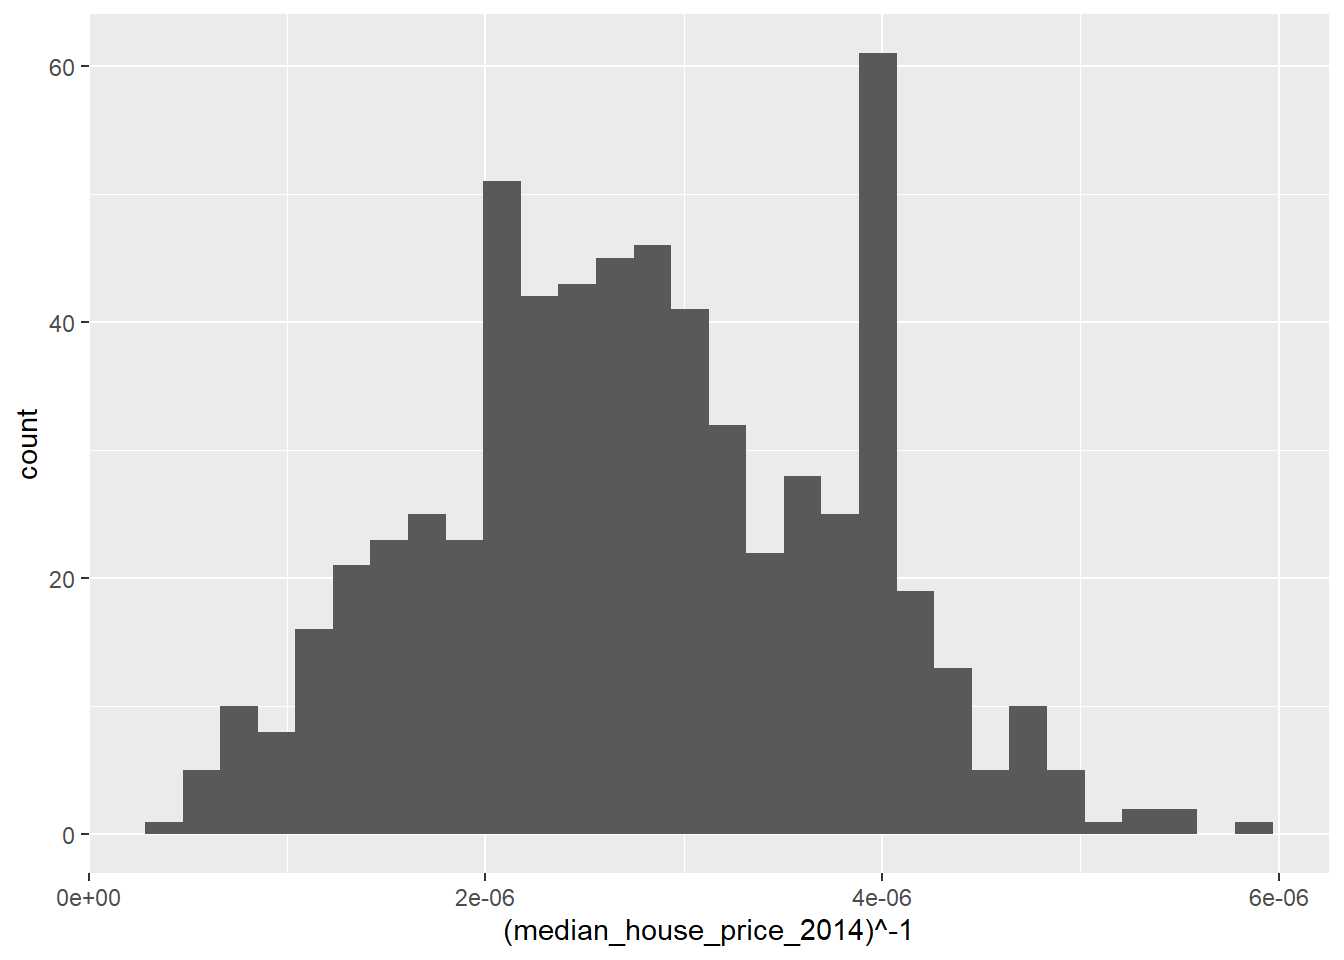
Depending on if the independent or dependent (GCSE point score) variables have been transformed depends on how we interpret them - see these rules for interpretation
8.5.8.2 Should I transform my variables?
The decision is down to you as the modeller - it might be that a transformation doesn’t succeed in normalising the distribution of your data or that the interpretation after the transformation is problematic, however it is important not to violate the assumptions underpinning the regression model or your conclusions may be on shaky ground.
Be careful The purpose of doing theses transformations is to make your data normally distributed, however you will be changing the relationship of your data - it won’t be linear anymore! This could improve your model but is at the expense of interpretation. Aside from log transformation which has the rules in the link above.
Typically if you do a power transformation you can keep the direction of the relationship (positive or negative) and the t-value will give an idea of the importance of the variable in the model - that’s about it!
For more information here read Transforming Variables in Regression by Eric van Holm, 2021
8.5.9 Assumption 2 - The residuals in your model should be normally distributed
This assumption is easy to check. When we ran our Model1 earlier, one of the outputs stored in our Model 1 object is the residual value for each case (Ward) in your dataset. We can access these values using augment() from broom which will add model output to the original GCSE data…
We can plot these as a histogram and see if there is a normal distribution:
#save the residuals into your dataframe
model_data <- model1 %>%
augment(., Regressiondata)
#plot residuals
model_data%>%
dplyr::select(.resid)%>%
pull()%>%
qplot()+
geom_histogram() 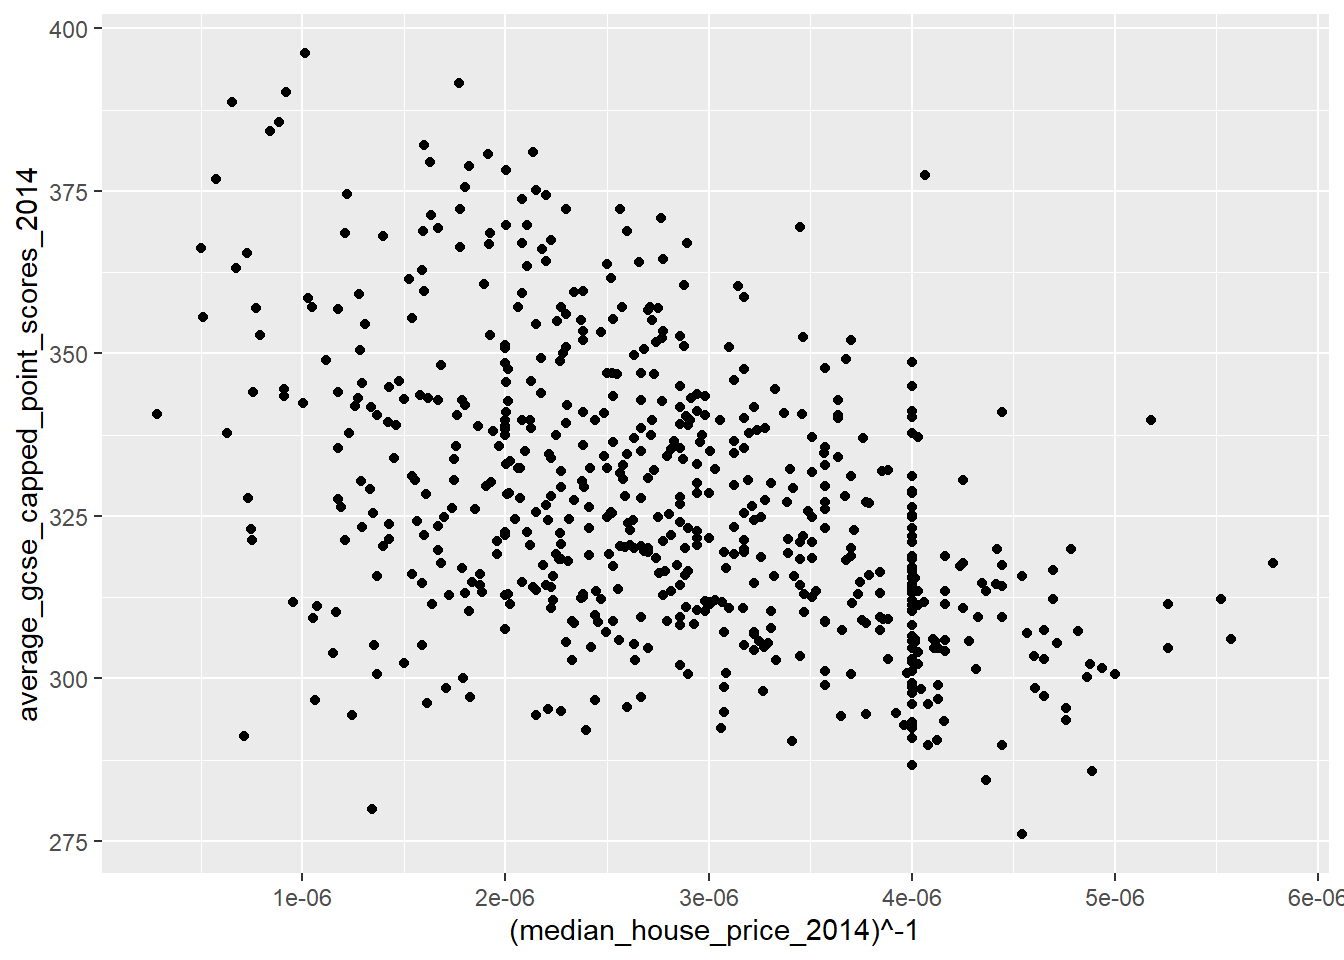
Examining the histogram above, we can be happy that our residuals look to be relatively normally distributed.
8.5.10 Assumption 3 - No Multicolinearity in the independent variables
Now, the regression model we have be experimenting with so far is a simple bivariate (two variable) model. One of the nice things about regression modelling is while we can only easily visualise linear relationships in a two (or maximum 3) dimension scatter plot, mathematically, we can have as many dimensions / variables as we like.
As such, we could extend model 1 into a multiple regression model by adding some more explanatory variables that we think could affect GSCE scores. Let’s try the log or ^-1 transformed house price variable from earlier (the rationale being that higher house prices indicate more affluence and therefore, potentially, more engagement with education):
Regressiondata2<- LonWardProfiles%>%
clean_names()%>%
dplyr::select(average_gcse_capped_point_scores_2014,
unauthorised_absence_in_all_schools_percent_2013,
median_house_price_2014)
model2 <- lm(average_gcse_capped_point_scores_2014 ~ unauthorised_absence_in_all_schools_percent_2013 +
log(median_house_price_2014), data = Regressiondata2)
#show the summary of those outputs
tidy(model2)## # A tibble: 3 × 5
## term estimate std.error statistic p.value
## <chr> <dbl> <dbl> <dbl> <dbl>
## 1 (Intercept) 202. 20.1 10.0 4.79e-22
## 2 unauthorised_absence_in_all_schools_per… -36.2 1.92 -18.9 3.71e-63
## 3 log(median_house_price_2014) 12.8 1.50 8.50 1.37e-16## # A tibble: 1 × 12
## r.squared adj.r.squared sigma statistic p.value df logLik AIC BIC
## <dbl> <dbl> <dbl> <dbl> <dbl> <dbl> <dbl> <dbl> <dbl>
## 1 0.483 0.482 15.5 291. 4.78e-90 2 -2604. 5215. 5233.
## # ℹ 3 more variables: deviance <dbl>, df.residual <int>, nobs <int>#and for future use, write the residuals out
model_data2 <- model2 %>%
augment(., Regressiondata2)
# also add them to the shapelayer
LonWardProfiles <- LonWardProfiles %>%
mutate(model2resids = residuals(model2))Examining the output above, it is clear that including median house price into our model improves the fit from an \(r^2\) of around 42% to an \(r^2\) of 48%. Median house price is also a statistically significant variable.
But do our two explanatory variables satisfy the no-multicoliniarity assumption? If not and the variables are highly correlated, then we are effectively double counting the influence of these variables and overstating their explanatory power.
](prac8_images/multicollinearity_explain.png)
Figure 8.1: Word anatomy of multicollinearity. Source: What the Heck is Multicollinearity?, Andrew Ozbun
To check this, we can compute the product moment correlation coefficient between the variables, using the corrr() pacakge, that’s part of tidymodels. In an ideal world, we would be looking for something less than a 0.8 correlation
library(corrr)
Correlation <- LonWardProfiles %>%
st_drop_geometry()%>%
dplyr::select(average_gcse_capped_point_scores_2014,
unauthorised_absence_in_all_schools_percent_2013,
median_house_price_2014) %>%
mutate(median_house_price_2014 =log(median_house_price_2014))%>%
correlate() %>%
# just focus on GCSE and house prices
focus(-average_gcse_capped_point_scores_2014, mirror = TRUE)
#visualise the correlation matrix
rplot(Correlation)## Warning: `aes_string()` was deprecated in ggplot2 3.0.0.
## ℹ Please use tidy evaluation idioms with `aes()`.
## ℹ See also `vignette("ggplot2-in-packages")` for more information.
## ℹ The deprecated feature was likely used in the corrr package.
## Please report the issue at
## <https://github.com/tidymodels/corrr/issues>.
## This warning is displayed once per session.
## Call `lifecycle::last_lifecycle_warnings()` to see where this
## warning was generated.
Looking at either the correlation matrix or the correlation plot of that matrix, it’s easy to see that there is a low correlation (around 30%) between our two independent variables. However, at this stage we might wish to introduce more variables into our model to improve our prediction of the dependent variable (GCSE scores), this is called Multiple Linear Regression (MLR). If you are unfamiliar with multiple linear regression consult the brief multiple linear regression section under the Extra content.
8.5.10.1 Variance Inflation Factor (VIF)
Another way that we can check for Multicolinearity is to examine the VIF for the model. If we have VIF values for any variable exceeding 10, then we may need to worry and perhaps remove that variable from the analysis:
## unauthorised_absence_in_all_schools_percent_2013
## 1.105044
## log(median_house_price_2014)
## 1.105044Both the correlation plots and examination of VIF indicate that our multiple regression model meets the assumptions around multicollinearity and so we can proceed further.
If we wanted to add more variables into our model, it would be useful to check for multicollinearity amongst every variable we want to include, we can do this by computing a correlation matrix for the whole dataset or checking the VIF after running the model:
position <- c(10:74)
Correlation_all<- LonWardProfiles %>%
st_drop_geometry()%>%
dplyr::select(position)%>%
correlate()## Warning: Using an external vector in selections was deprecated in tidyselect
## 1.1.0.
## ℹ Please use `all_of()` or `any_of()` instead.
## # Was:
## data %>% select(position)
##
## # Now:
## data %>% select(all_of(position))
##
## See
## <https://tidyselect.r-lib.org/reference/faq-external-vector.html>.
## This warning is displayed once per session.
## Call `lifecycle::last_lifecycle_warnings()` to see where this
## warning was generated.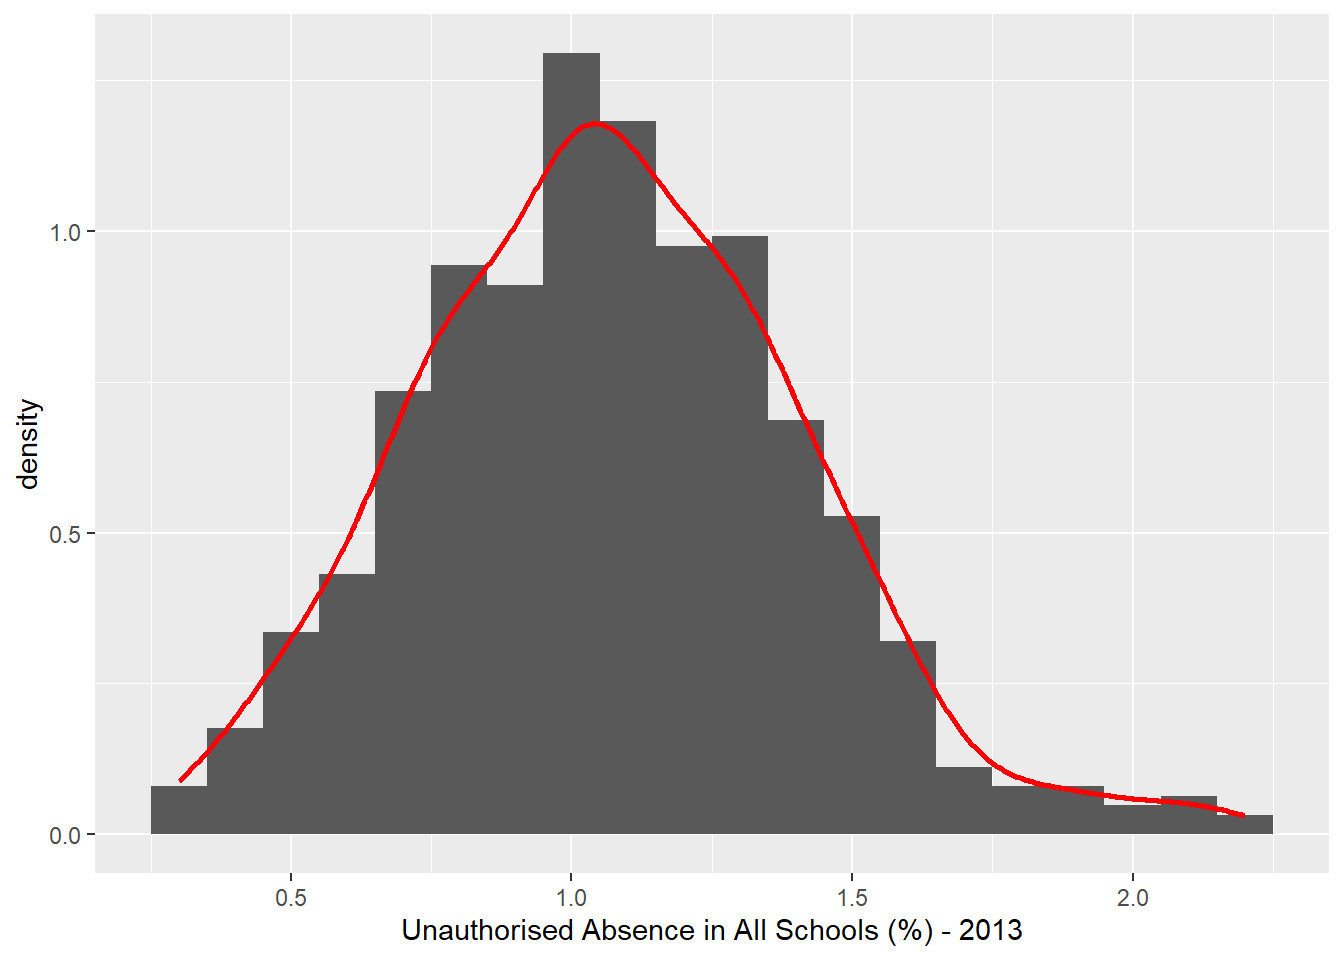
8.5.11 Assumption 4 - Homoscedasticity
Homoscedasticity means that the errors/residuals in the model exhibit constant / homogenous variance, if they don’t, then we would say that there is hetroscedasticity present. Why does this matter? Andy Field does a much better job of explaining this in discovering statistics — but essentially, if your errors do not have constant variance, then your parameter estimates could be wrong, as could the estimates of their significance.
The best way to check for homo/hetroscedasticity is to plot the residuals in the model against the predicted values. We are looking for a cloud of points with no apparent patterning to them.
In the series of plots above, the first plot (residuals vs fitted), we would hope to find a random cloud of points with a straight horizontal red line. Looking at the plot, the curved red line would suggest some hetroscedasticity, but the cloud looks quite random. Similarly we are looking for a random cloud of points with no apparent patterning or shape in the third plot of standardised residuals vs fitted values. Here, the cloud of points also looks fairly random, with perhaps some shaping indicated by the red line.
Section 5.7.6 in Tidyverse Skills for Data Science explains each of these plots in more detail
In the plots here we are looking for:
Residuals vs Fitted: a flat and horizontal line. This is looking at the linear relationship assumption between our variables
Normal Q-Q: all points falling on the line. This checks if the residuals (observed minus predicted) are normally distributed
Scale vs Location: flat and horizontal line, with randomly spaced points. This is the homoscedasticity (errors/residuals in the model exhibit constant / homogeneous variance). Are the residuals (also called errors) spread equally along all of the data.
Residuals vs Leverage - Identifies outliers (or influential observations), the three largest outliers are identified with values in the plot.
The University of Viginia Library provides examples of good and bad models in relation to these plots.
There is an easier way to produce this plot using check_model() from the performance package, that even includes what you are looking for…note that the Posterior predictive check is the comparison between the fitted model and the observed data.
The default argument is check=all but we can specify what to check for…see the arguments section in the documentation…e.g. check = c("vif", "qq")
## Warning: package 'performance' was built under R version 4.5.3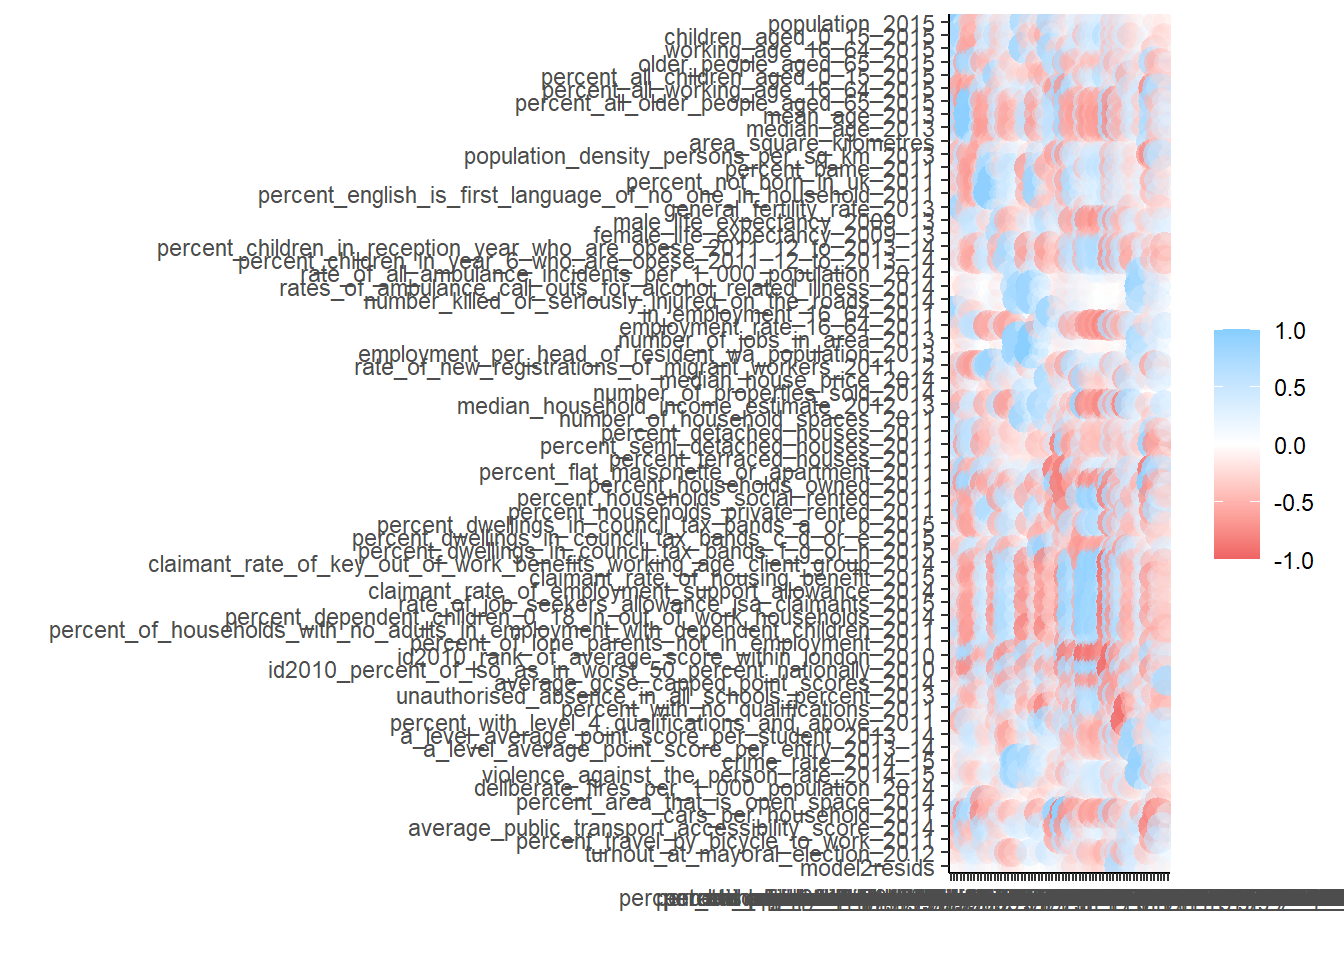
8.5.12 Assumption 5 - Independence of Errors
This assumption simply states that the residual values (errors) in your model must not be correlated in any way. If they are, then they exhibit autocorrelation which suggests that something might be going on in the background that we have not sufficiently accounted for in our model.
8.5.12.1 Standard Autocorrelation
If you are running a regression model on data that do not have explicit space or time dimensions, then the standard test for autocorrelation would be the Durbin-Watson test.
This tests whether residuals are correlated and produces a summary statistic that ranges between 0 and 4, with 2 signifiying no autocorrelation. A value greater than 2 suggesting negative autocorrelation and and value of less than 2 indicating postitve autocorrelation.
In his excellent text book, Andy Field suggests that you should be concerned with Durbin-Watson test statistics <1 or >3. So let’s see:
## # A tibble: 1 × 5
## statistic p.value autocorrelation method alternative
## <dbl> <dbl> <dbl> <chr> <chr>
## 1 1.61 0 0.193 Durbin-Watson Test two.sidedAs you can see, the DW statistics for our model is 1.61, so some indication of autocorrelation, but perhaps nothing to worry about.
HOWEVER
We are using spatially referenced data and as such we should check for spatial-autocorrelation.
The first test we should carry out is to map the residuals to see if there are any apparent obvious patterns: